Extract Text data from image-only PDF file
INFORMATION
SKILLS: Computer Vision, CV2, Tesseract, OCR, Regex
Link: Private
CREATED: 2023-10-10
PROJECT DESCRIPTION
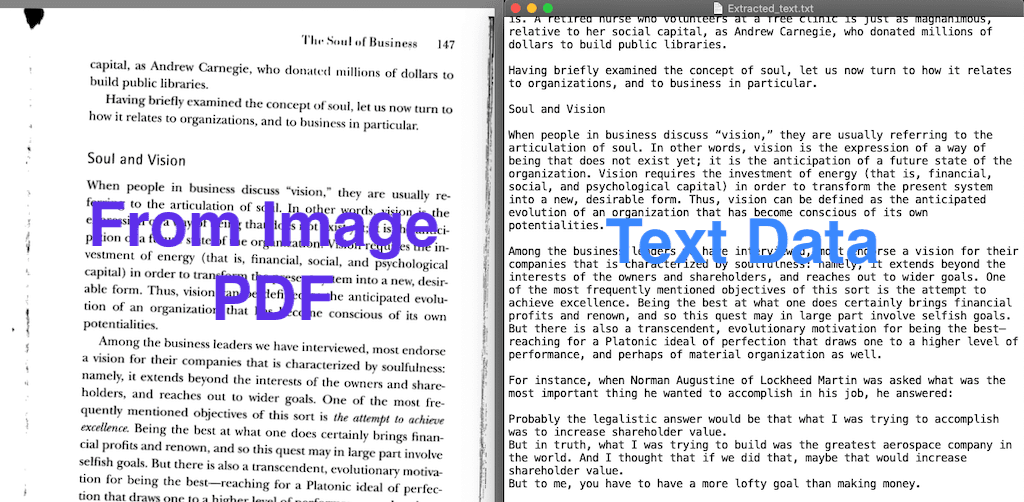
Text cannot be selected in PDF files that only contain images without embedded text data, so copying, pasting, and machine translation are not possible. And also voice reading on smartphones and browsers does not work. To solve these problems, create a program that automatically extracts text. First, extract all images from the PDF. Automatically corrects the distortion of tilted images to improve OCR accuracy. It automatically detects and removes redundant areas such as headers, footers, and margins. Extract text from the cleaned image using OCR. The extracted text is converted into words by removing hyphens and unnecessary spaces. It can convert hundreds of pages of PDF files into text data at once.